How does a RAG pipeline work?
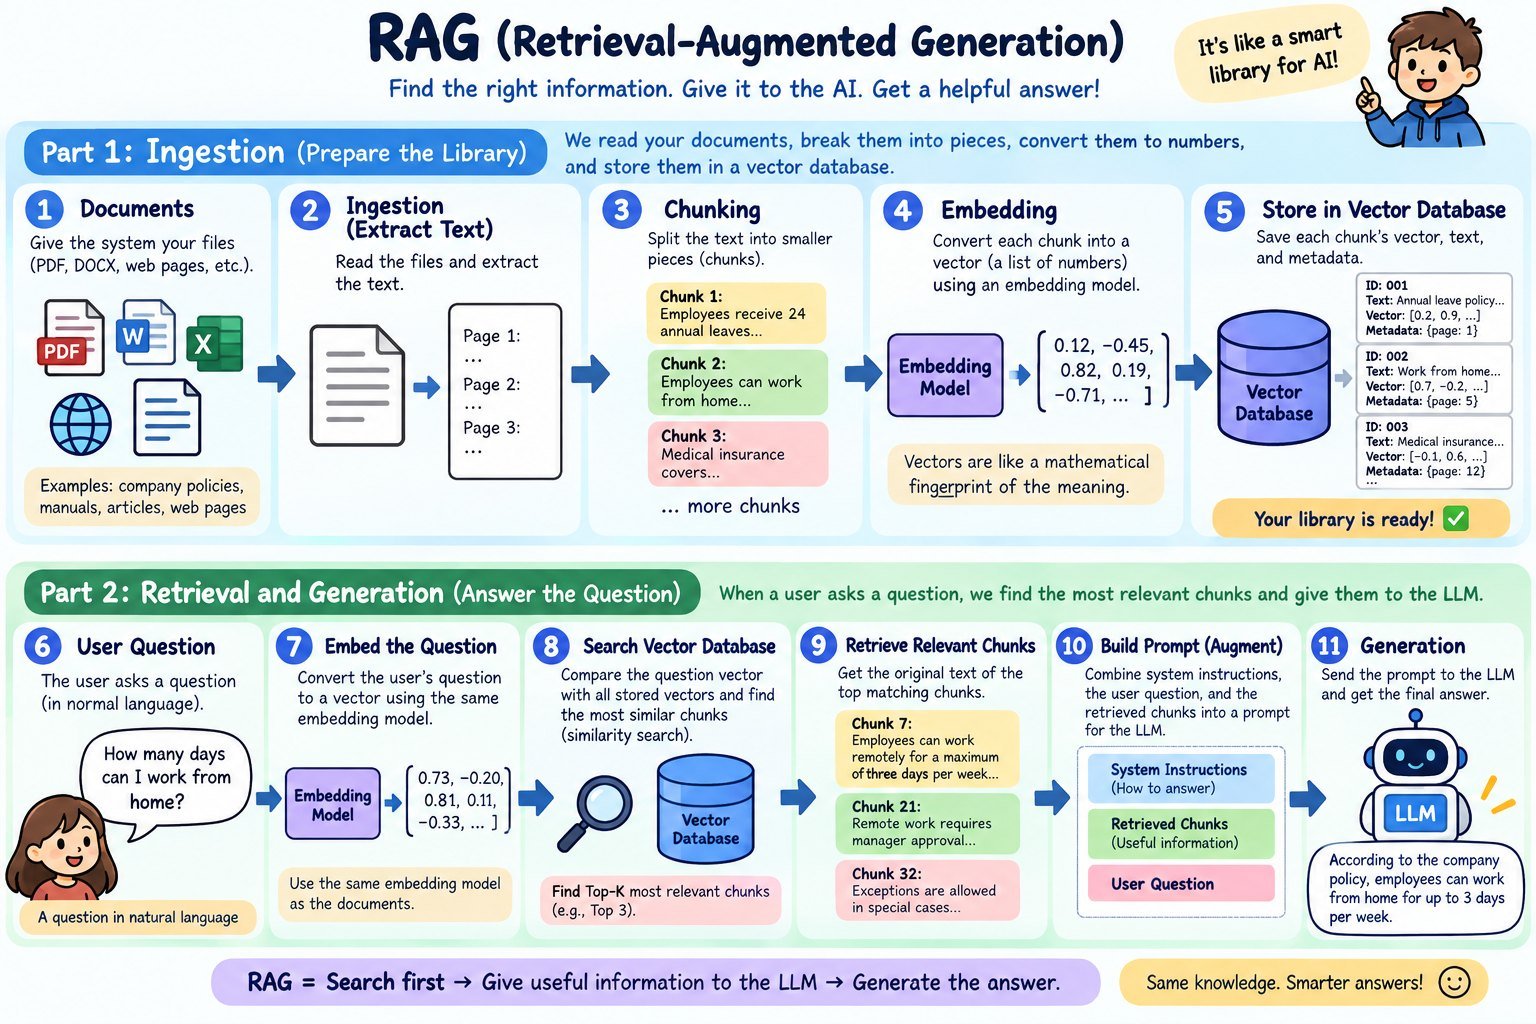
A RAG pipeline works in two stages. First, documents are split into chunks, turned into embeddings and stored in a vector database. Then, when a user asks a question, the system finds the most similar chunks and gives them to the LLM to generate the answer.
RAG looks complicated… until you see the pipeline.
Documents → Chunking → Embeddings → Vector DB
User Query → Similarity Search → Relevant Chunks → LLM → Answer
That’s Retrieval-Augmented Generation (RAG) in one picture.
The key idea?
Don’t ask AI to know everything. Help it find the right information first.
Read the conversation and GenAI scenario-based interview question here:
https://www.aiplaybookhub.com/books/genai-testing-for-qa.html