What is LLM-as-Judge? Can AI evaluate another AI? (GenAI testing interview question)
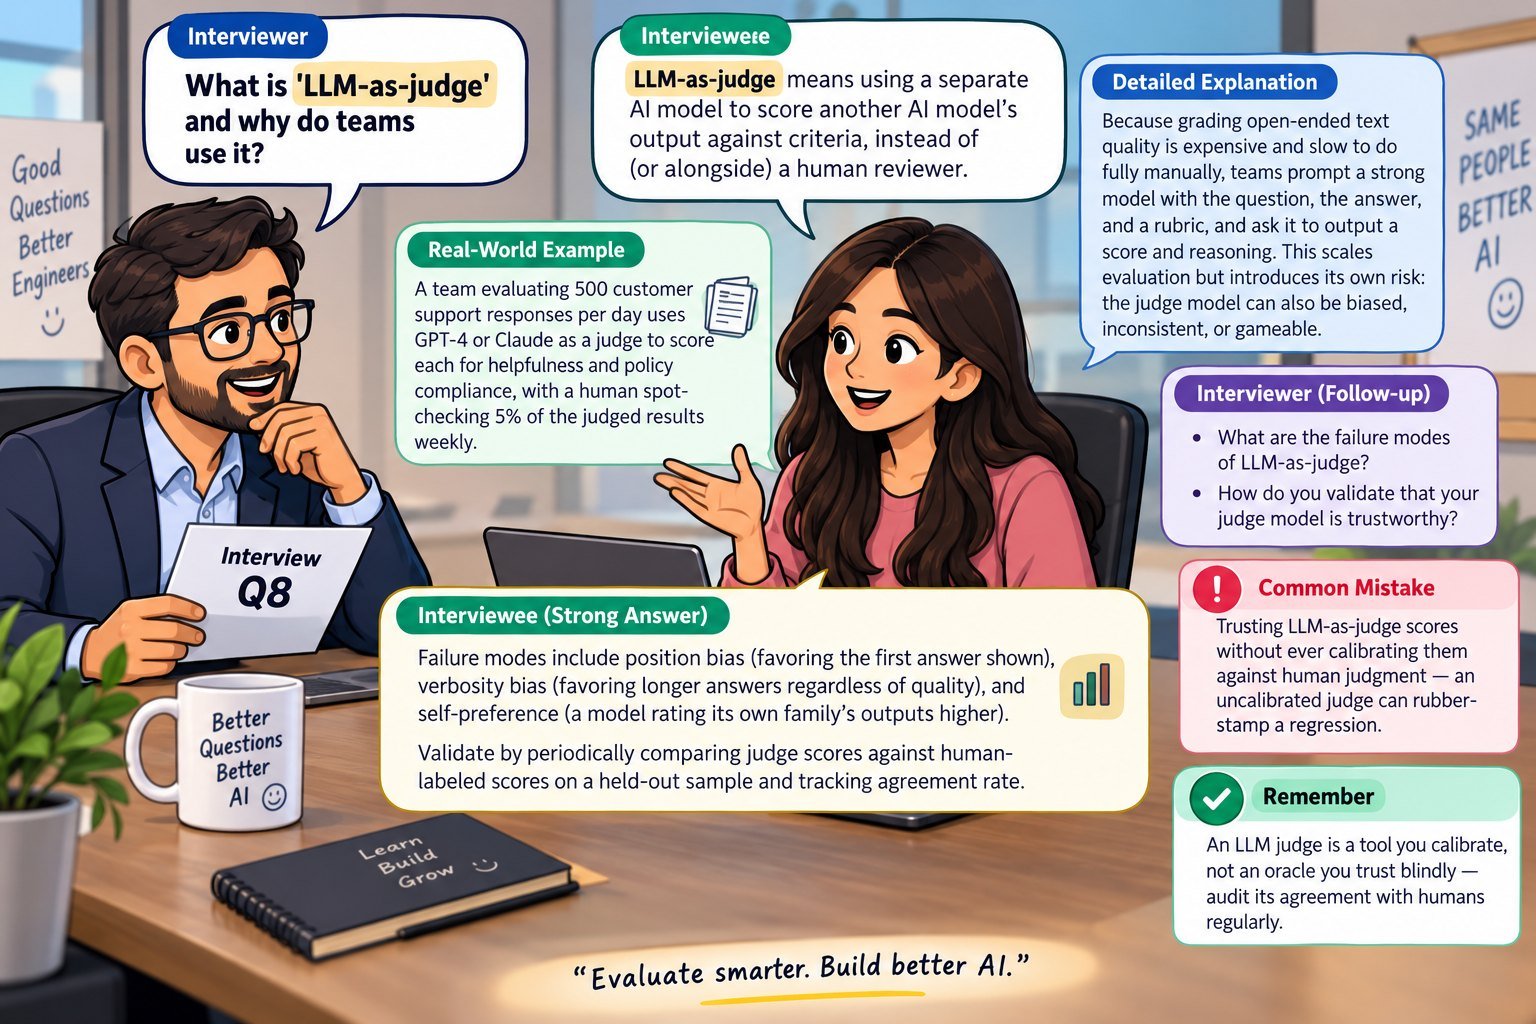
LLM-as-Judge is a testing method where one AI model scores another model's responses against criteria like accuracy, relevance or tone. It scales evaluation, but the judge can be biased or inconsistent, so its scores must be checked against human judgment.
Yes! Meet LLM-as-Judge — where one AI model evaluates another AI model’s responses.
But here's the catch!
An AI judge can also be biased, inconsistent, or wrong.
The QA Lesson: Never blindly trust AI-generated scores. Validate them against human judgment.
Because testing AI requires more than just AI!
Have you used LLM-as-Judge in your testing projects?
Read Basic knowledge and real world interview questions here-
https://www.aiplaybookhub.com/books/genai-testing-for-qa.html
Kindle version-https://lnkd.in/diWhse3w