What is RLHF (Reinforcement Learning from Human Feedback)? Explained with a QA example (interview question)
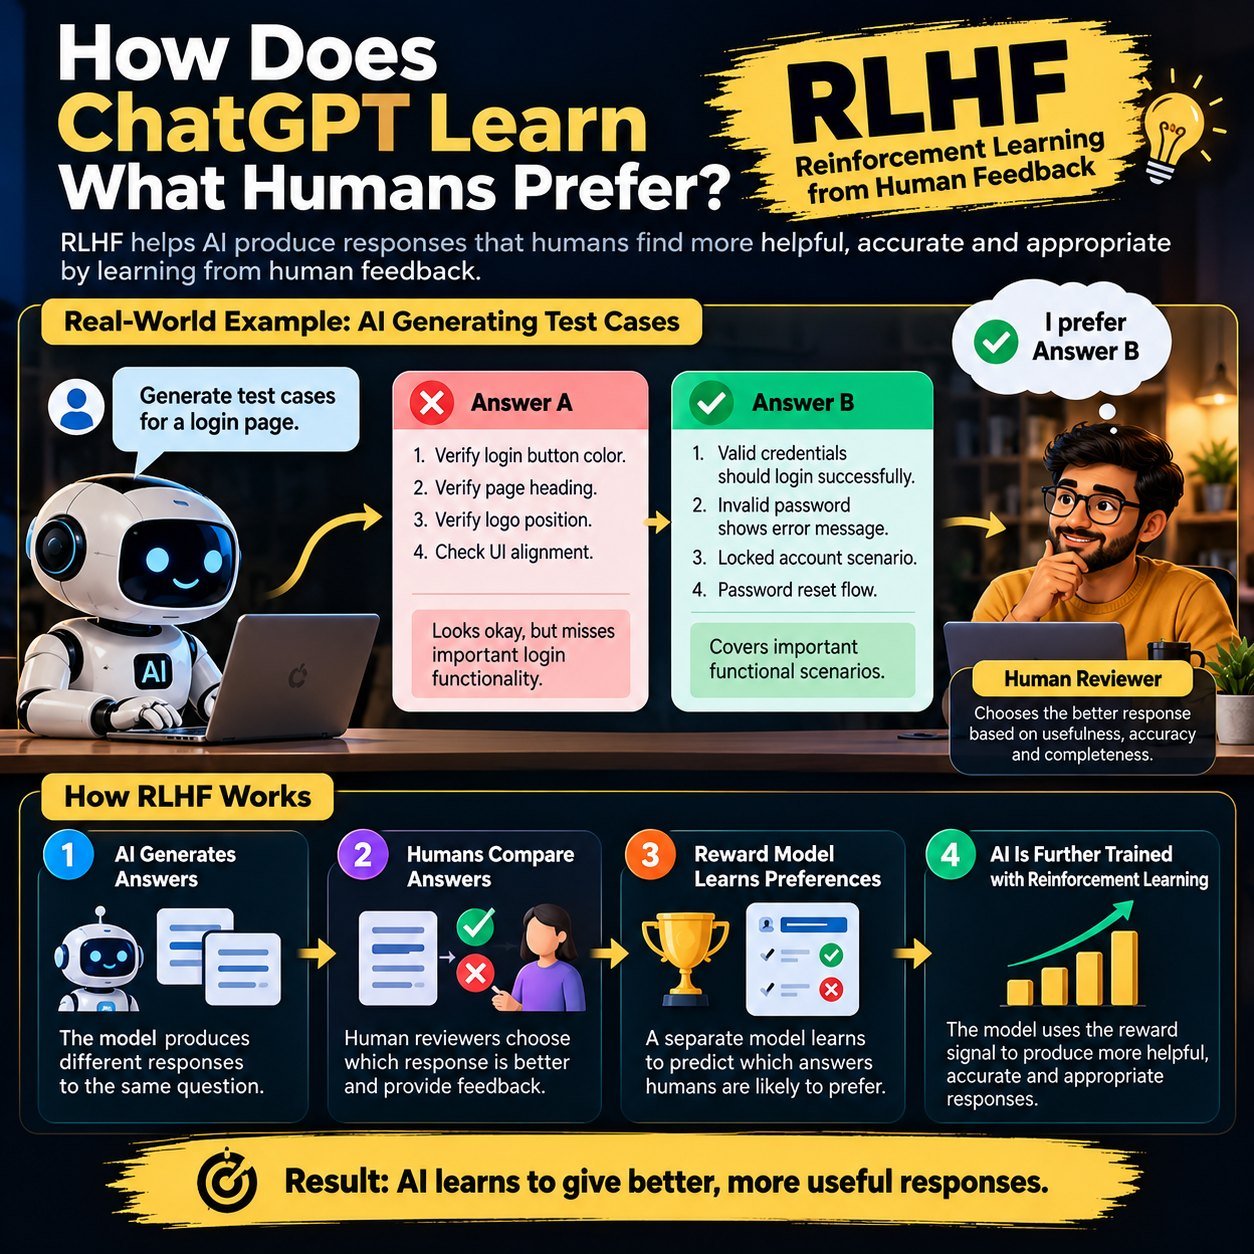
RLHF trains AI using human preferences as well as data. People compare answers and choose the more useful one. Those choices train a reward model, and the reward model then steers the AI towards more helpful responses.
Daily Dose of AI | How Do AI Tools Learn What Humans Prefer?
Ever wondered how AI learns to give better answers?
AI doesn't just learn from data. It can also learn from human preferences!
PROBLEM: AI may generate answers that sound correct but aren't useful.
SOLUTION: Meet RLHF — Reinforcement Learning from Human Feedback.
Real Example: Ask AI: Generate login test cases.
Answer A: Check button color, logo, and heading.
Answer B: Check valid login, invalid password, and locked account.
A QA expert prefers Answer B because it covers important functional scenarios. That human preference can help train a reward model, which guides further AI training.🎯
RESULT: AI learns to favor more helpful and relevant responses.
Remember: Human Feedback → Better Training Signals → Better AI Responses
If you were training an AI testing assistant, what would you reward most — accuracy, coverage, or clarity?
Explore ebooks on AI here ->https://lnkd.in/dyArasuM