What is AI Agent Evals?
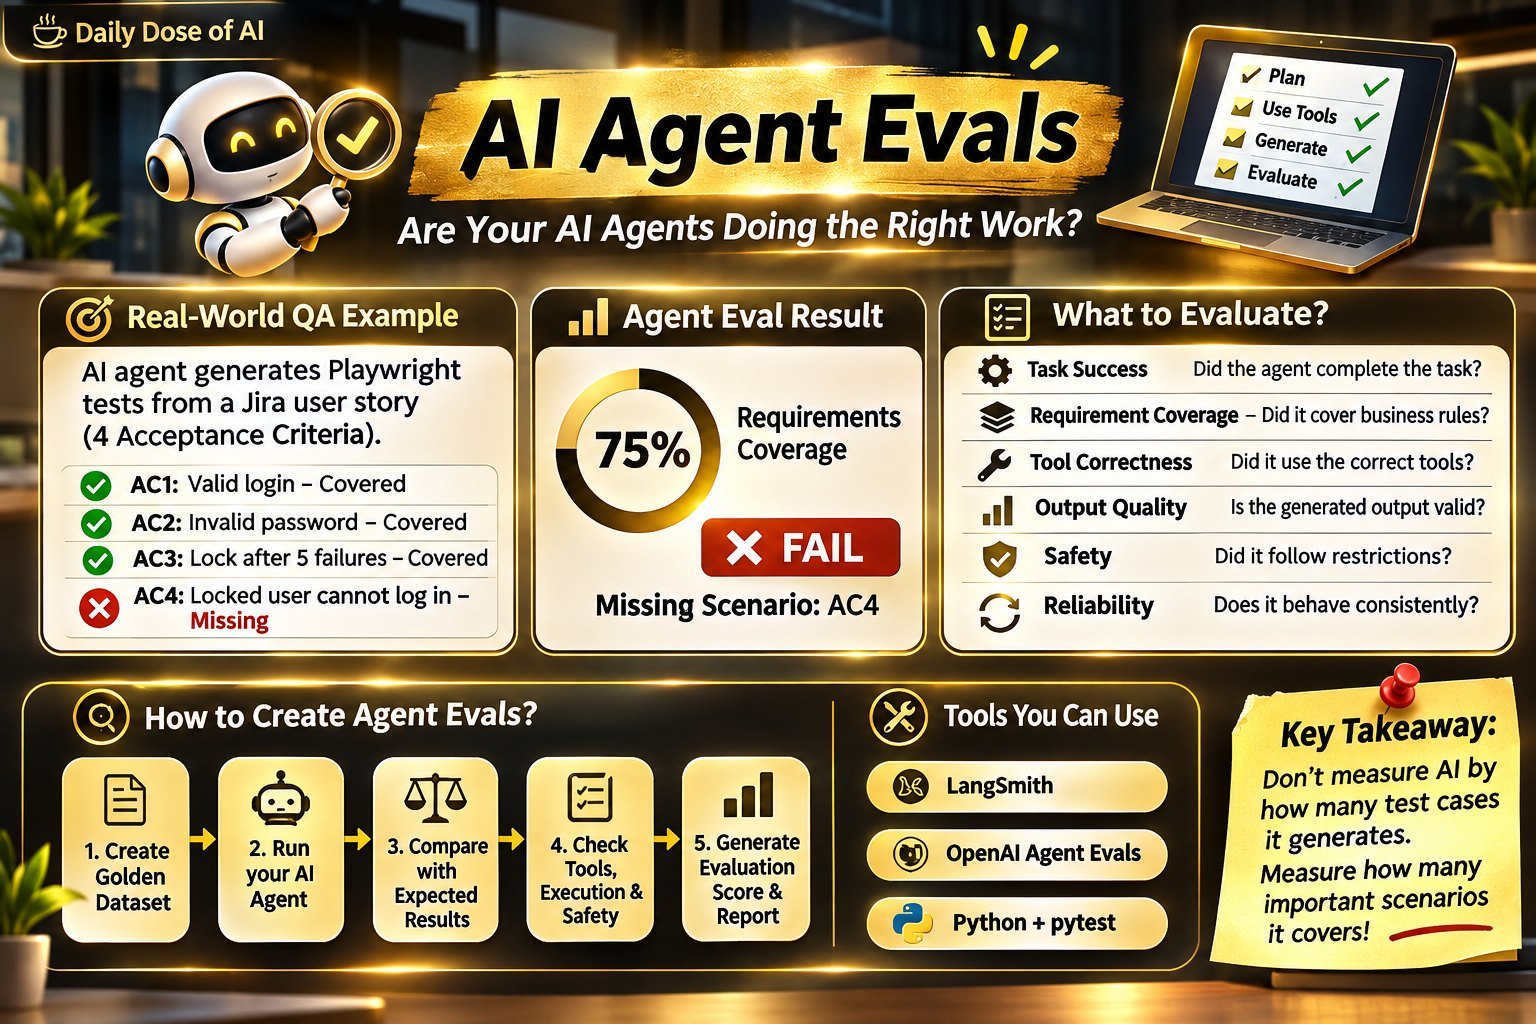
Your AI Agent generated 20 test cases. But did it cover the right scenarios?
That's where AI Agent Evals come in!
Real-World QA Example:
Imagine an AI agent generating Playwright tests from a Jira user story.
The story has 4 acceptance criteria.
✅ Valid login — Covered
✅ Invalid password — Covered
✅ Account lock after 5 failures — Covered
❌ Locked user login — Missing!
📊 Agent Eval Result:
Requirements Coverage: 75%
Missing Scenario: AC4
Evaluation Status: ❌ FAIL
🛠️ How to Create Agent Evals?
1️⃣ Create a Golden Dataset (expected scenarios).
2️⃣ Run your AI Agent.
3️⃣ Compare generated tests against expected results.
4️⃣ Check tool usage, test execution, and safety rules.
5️⃣ Generate an evaluation score and report.
💡 Tools: LangSmith | OpenAI Agent Evals | Python + pytest
🎯 Key Takeaway:
Don't measure AI by how many test cases it generates. Measure how many important scenarios it covers!
💬 Are you evaluating your AI agents or simply trusting their outputs?
📚 More AI concepts: https://lnkd.in/gPKyssA4